
Inside ExtractBench: Benchmarking Document Extraction for Agents
LlamaIndex
42:27
Existing benchmarks for schema-guided document extraction weren’t built for workflows where agents act on the output. They measure only a slice of the task and miss the failure modes that matter in production.
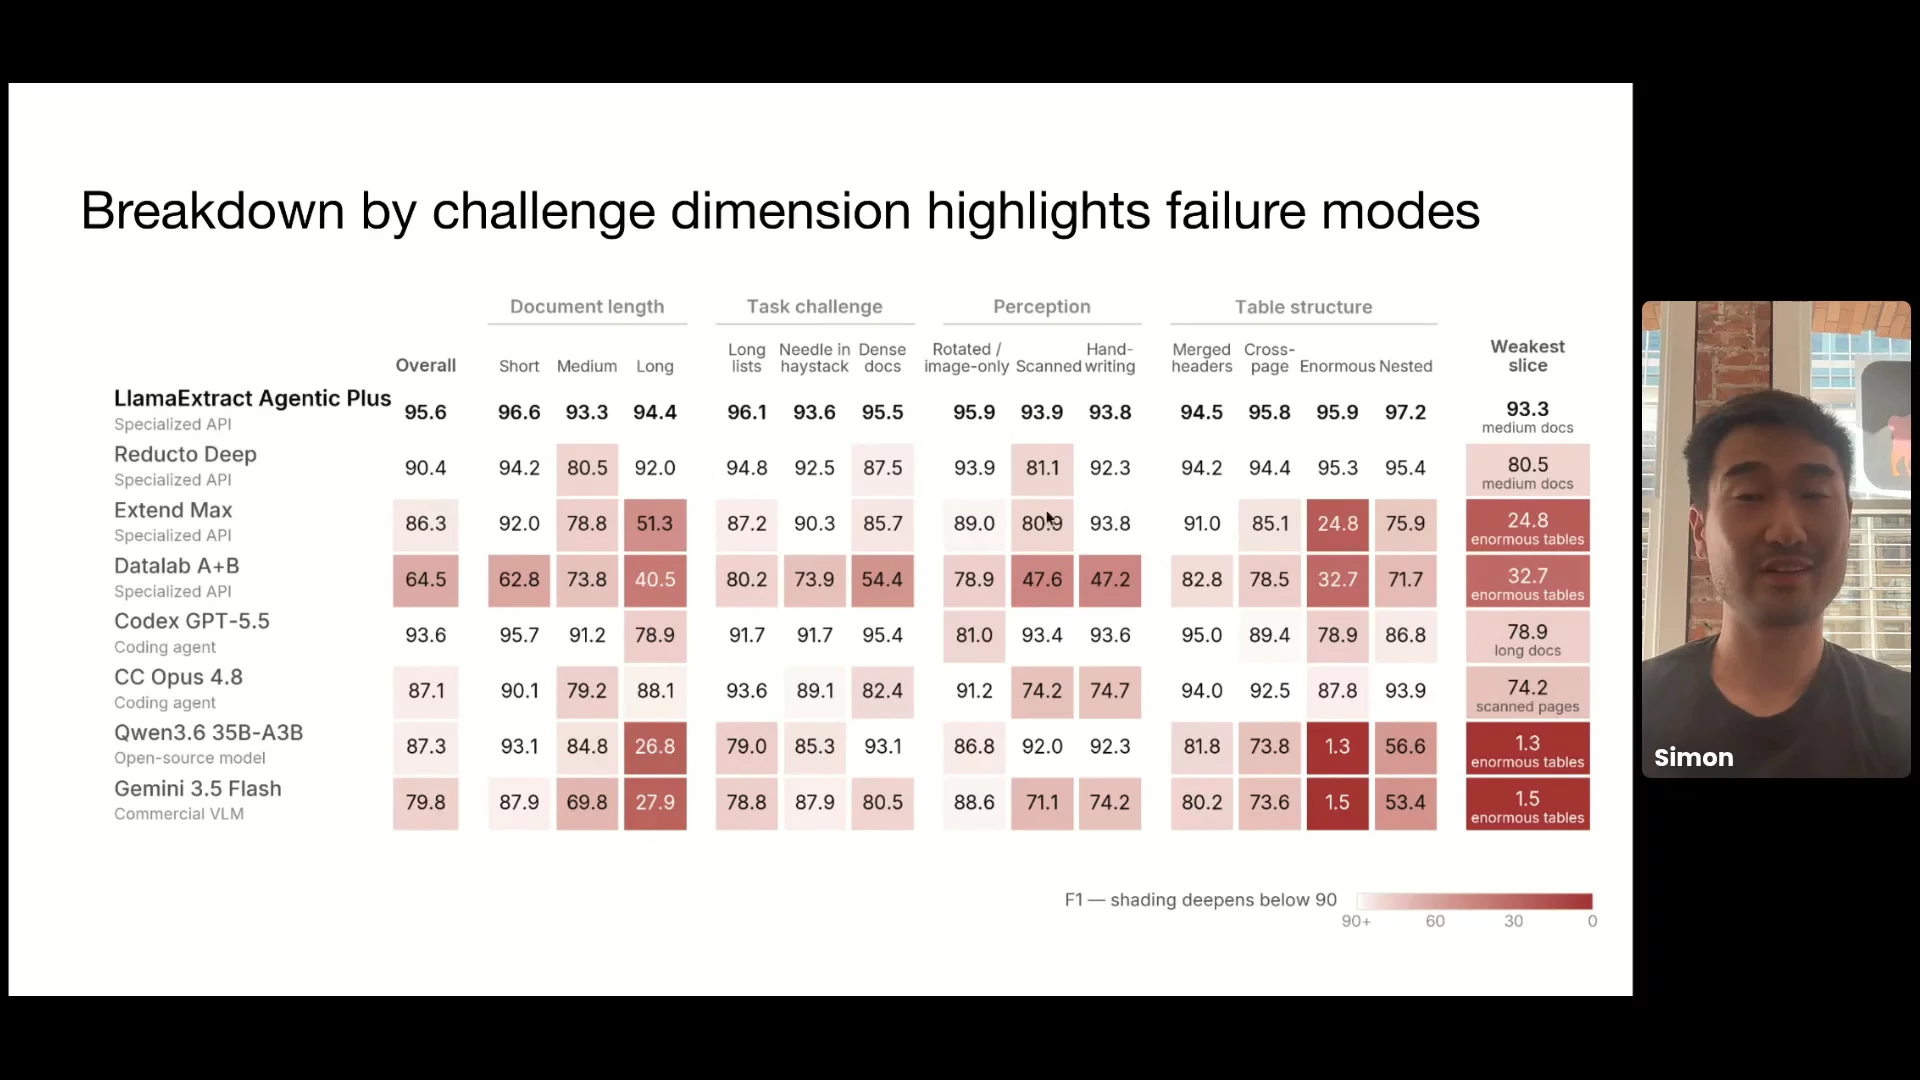
Join Simon Suo, CTO and co-founder of LlamaIndex, for a technical walkthrough of ExtractBench, a new benchmark evaluating 14 frontier systems across 370 enterprise documents, 67 document types, and 4,800+ pages. He’ll cover the real-world failure modes that shaped it, the trade-offs between VLMs and coding agents, and what testing top systems revealed.
You will learn:
- How document extraction evaluation has evolved, and where existing benchmarks fall short
- What makes document extraction hard and how to measure that difficulty
- How cost scales with accuracy across VLMs, coding agents and specialized APIs
- How to structure robust extraction evals around your own documents and schemas
Speaker

Simon Suo
CTO, LlamaIndex
Inside ExtractBench: Benchmarking Document Extraction for Agents
42:27